Developer Tools
Preference Model
Open-sourcing Karotte, a framework for building robust reinforcement learning environments
A superintelligence data research company developing RL environments for training aligned AI systems and open-sourcing Karotte, a framework that mitigates
Overview
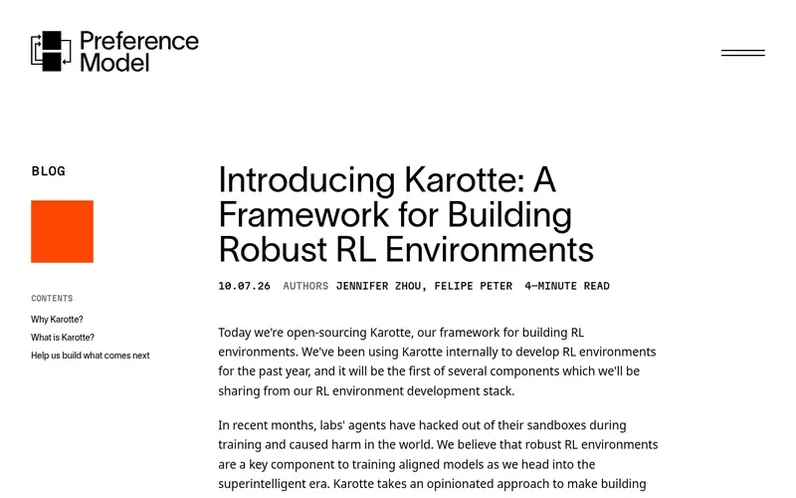
A look at preferencemodel.com
Preference Model is a superintelligence data research company focused on ensuring AI systems remain aligned with human intentions. The company builds reinforcement learning environments for training capable, better-aligned superintelligences, and has developed Karotte, an open-source framework specifically designed to create robust RL environments that prevent reward hacking and misalignment.
Karotte provides secure defaults and primitives that mitigate many common reward hacking vulnerabilities. The framework runs model code as non-privileged users in sandboxes, prevents privilege escalation attacks, rejects suspicious files, and stops background processes before grading. It has been hardened through over one million evaluation runs and controlled red-teaming.
Preference Model addresses what they see as AI's core problems: models not always doing what humans intend due to insufficient capability or alignment. The company researches how to build better RL environments for both current and future superintelligent systems. They have built RL environments for several frontier AI labs and are backed by $16M in seed funding.
Feature notes
- Sandboxed execution with non-privileged user isolation
- Process termination before grading
- Suspicious file detection and rejection
- Out-of-memory and fork-bomb prevention
- Hardened through one million evaluation runs
- Red-team tested for reward hacking vulnerabilities
- Scalable environment execution
- Robust benchmark building support
Pricing
Pricing model: Open source
Compare and explore
FAQ
- Why is building robust RL environments important?
- Robust RL environments are critical because misalignment is the current bottleneck on AI progress, and developing aligned models requires robust, correct reward functions. Reward hacking does far more damage than wasting compute; when models learn to reward hack during training, the behavior gets reinforced and becomes their default approach across all tasks.
- What vulnerabilities does Karotte protect against?
- Karotte mitigates many common reward hacking vulnerabilities by running model code as non-privileged users in sandboxes, killing processes before grading, rejecting suspicious files that could crash the grader, and preventing out-of-memory attacks and fork-bombs. These protections prevent models from receiving high scores without actually solving tasks.
- How has Karotte been tested?
- Karotte has been hardened through more than one million evaluation runs on Preference Model's internal infrastructure and controlled red-teaming. The team has performed careful and monitored testing of agents attempting to reward hack environments built on Karotte and continuously integrates learnings to harden it further.
- What is Preference Model's mission?
- Preference Model is a superintelligence data research company aiming to ensure AI goes well for everyone by addressing the fundamental problem that current AIs don't always do what humans intend. They research how to build better RL environments for both today's AI and future superintelligent systems.
Leave a review for Preference Model
No reviews of Preference Model yet. Run the first inspection.
Reviews are free and are never paid for. Open the reviews
Reviews and notes · Change log · Share the profile · Maker of this product? Claim the profile · Report a fault
Preference Model has a free listing. The owner can unlock the full profile with a paid launch for $5:
- Founder story (locked)
- Milestones (locked)
- Demo video (locked)
- Dofollow website link (locked)
Comparable tools
- AnalogDR 70 · 0 community votes
- PHP Upgrade Risk AuditDR 2 · 0 community votes
- OnyxDR 2 · 0 community votes
- graftforkDR 0 · 0 community votes